

Every model’s price is public. Ten dollars per million input tokens for one, five for another, printed on the pricing page, exact to the cent. What the model will actually do for your work is printed nowhere: not on the leaderboard, not in the release notes. You know exactly what you will pay, and almost nothing about what you will get.
That gap, between what you can read and what you can only measure, is what this article is all about.
AI is unpredictable in a way people are not
With a person, skill is more or less predictable. A developer who handles a hard task will also handle the easier version of it. With AI models, this rule breaks. A model can do something that looks hard, and fail at something that looks easy. The border between “can” and “cannot” runs where nobody expects it.
Examples? Models still get simple time questions wrong: which of two deadlines comes first, or what happened before what in a changelog. The same model will do a mechanical change across two hundred files in minutes, or write the regex you would spend twenty minutes looking up. None of this follows the human sense of what is hard.
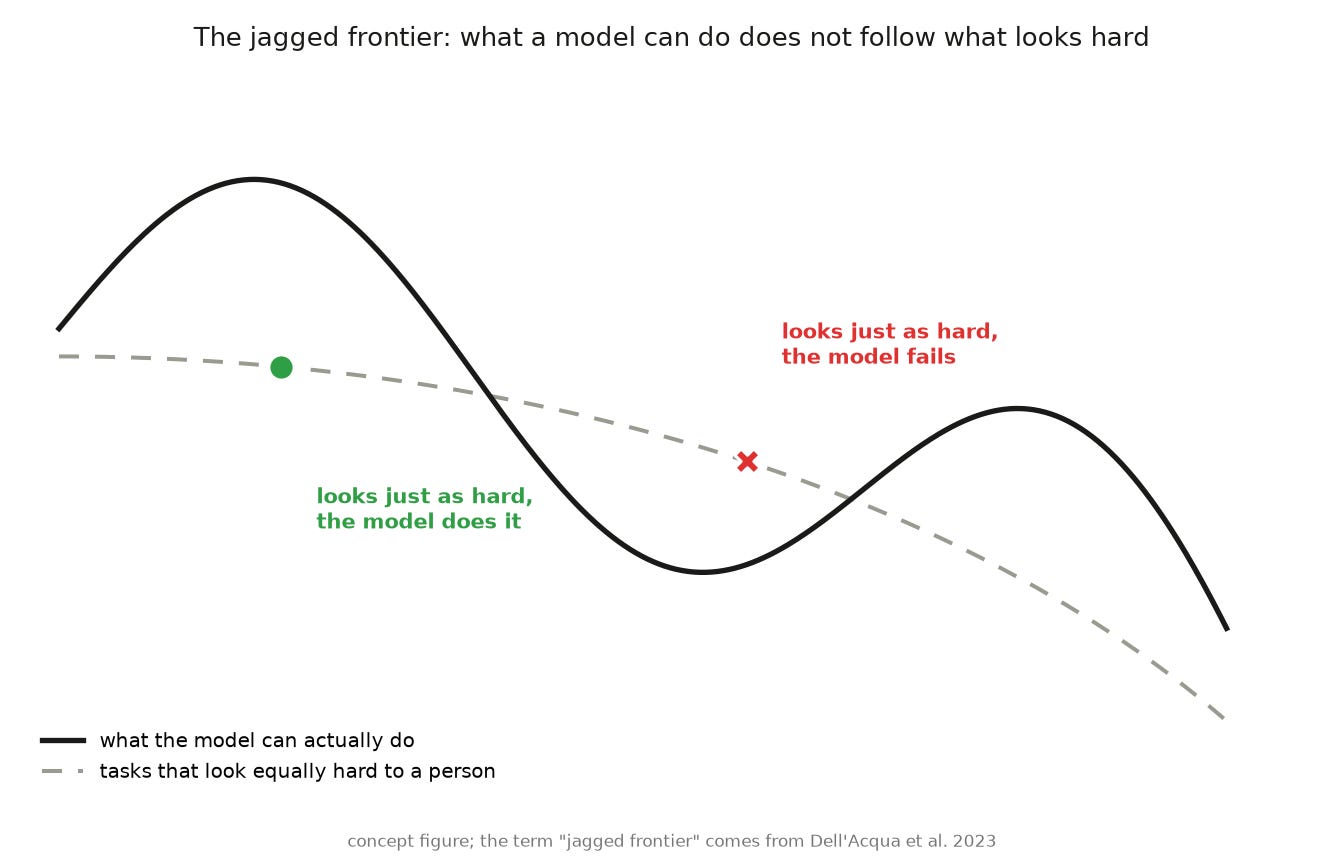
Researchers who studied this named the border the jagged frontier (Dell’Acqua et al., 2023).
Two more things make it harder. Every model has its own jagged shape, and the harness around the model reshapes it again: the tools it can call, the skills and instructions you add, the extra systems you connect over MCP. The same model in two different setups has two different frontiers. And every release redraws all of it. Release notes will not tell you where: they describe the whole shape as “better”. So the useful question is never “is the new model better”. It is “which parts of my work moved inside the frontier, and which did not”.
Who decides which model does your work?
Until recently, many developers had a simple answer: use the best model for everything. That was a sound default when usage was light and a flat subscription hid the bill. It stops working as AI costs grow. Agent workflows run longer, more work gets delegated, and the best-model-everywhere habit starts to cost real money. And “best” is not even well defined on a jagged frontier.
So the decision matters now. It just gets made differently in different setups.
If you work within one provider, say Anthropic, you are not using one model. You are using a lineup: a flagship (Fable), a strong workhorse (Opus), a mid tier (Sonnet), a fast tier (Haiku), plus effort settings on top of each. Every session quietly answers the question “which one is enough for this job?”, usually by habit. The frontier question lives inside a single vendor’s catalog too.
If you pick models per task across providers, your picks carry a mental map of who is good at what. That map came from somewhere: headlines, colleagues, one memorable failure.
And maybe a router picks for you, because you do not limit yourself to one provider at all. This happens in more places than most people notice: an auto mode in a coding tool, an aggregator that spreads requests across many providers and models, a company platform that decides centrally which model handles which request. In all these cases someone had to write a routing policy, and that policy is a map of what models are good at, written into someone else’s algorithm. Knowing your own terrain is how you decide when to trust the automatic choice and when to pin a model.
In every setup there is a policy: a habit, a feeling, or an algorithm. It rests on some picture of what models are good at. Today, that picture is mostly guesswork.
Three ways to replace the guesswork
How do you learn where your work sits on a model’s frontier? There are three honest ways. Each gives you more control and more understanding than the one before.
The vibe check. You try a model on your task and form an impression. Everyone does it, it works, and it deserves respect. But you cannot repeat it, it changes with mood and single stories, and it is gone when the next release lands. It leaves you no number to compare and no price to weigh. Other people’s vibe checks travel even worse: most public chatter comes from interactive coding sessions, and if your task is a different kind of work, those impressions describe a different terrain.
The analytical route. You dig through existing public benchmarks, find the tasks that look like yours, and work out where your work should sit. This is real expertise: the same work the authors of routing policies do when they decide which model gets which request. Its limit is built in: public benchmarks average over other people’s tasks, so your placement stays a guess. A weather forecast for the whole continent, when what you need is whether it will rain over your garden. Still, doing this work yourself is how you understand what any router is assuming on your behalf.
The private benchmark. This is simply the vibe check, automated. The same task you would have tried anyway, but with frozen inputs, checks written down, a few repetitions, and a price tag per run. Programmers have made this exact move before: manual testing became automated tests. A test suite is a manual check written down so it can run on every change; a private benchmark is the same thing, run against the models you are choosing between. It closes the loop the other two leave open: it measures your tasks, the same way every time. And it is the way to verify that the analytical mapping actually holds for your work.
A private benchmark is like an automated test - it is a vibe check you can rerun.
What we measured
Our recurring task is domain modeling on a real codebase: the model reads an existing system and implements a new business rule the way a careful senior developer would. The task is non-interactive: the model gets the codebase and the requirement, and works alone until done. We ran it through three models, Fable 5, Opus 4.8, and Opus 5, each in three instruction configurations: “vanilla” means the model gets only the task, “hint” adds one sentence of guidance (which is not a handicap - just an encouragement to think deeper), and “skill” adds a full instruction file about this type of work. Four runs per combination, 36 runs in total; each one priced according to real API costs.
The scores are built, not felt. Every run is graded by a panel of two judge models, two passes each, against a versioned rubric of 18 named checks: things a senior reviewer would look for. The judges write their verdicts in prose, so every score can be compared with its written reason. We ran and graded everything with NASDE, an open toolkit we built for this.
Here is the whole experiment on one chart. Every small dot is one run. Every large marker is the average of the four runs for one model and one configuration. Color is the model, shape is the configuration. Cost grows to the right, quality grows upward, so the best place to be is the top left corner.
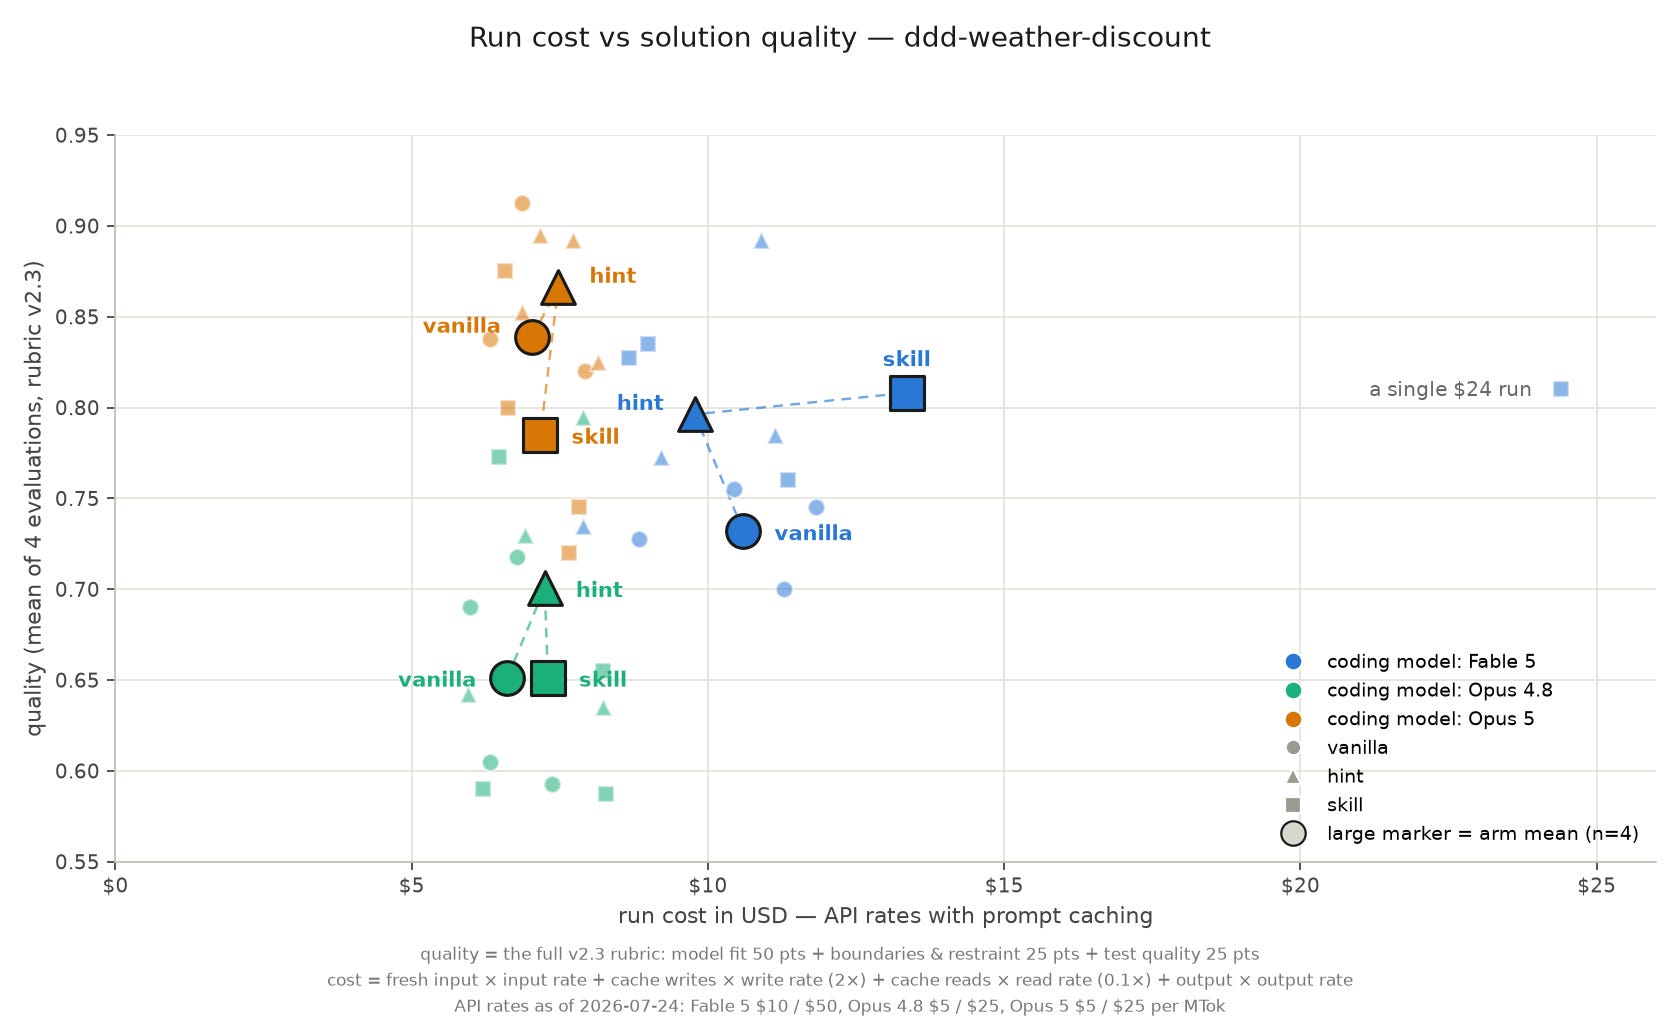
The orange points sitting high on the left are the short version of everything that follows: the cheapest of the three models did the best work.
What the map showed
Because quality breaks down into 18 named checks, the jagged frontier stops being a metaphor. You can see the jaggedness, row by row.
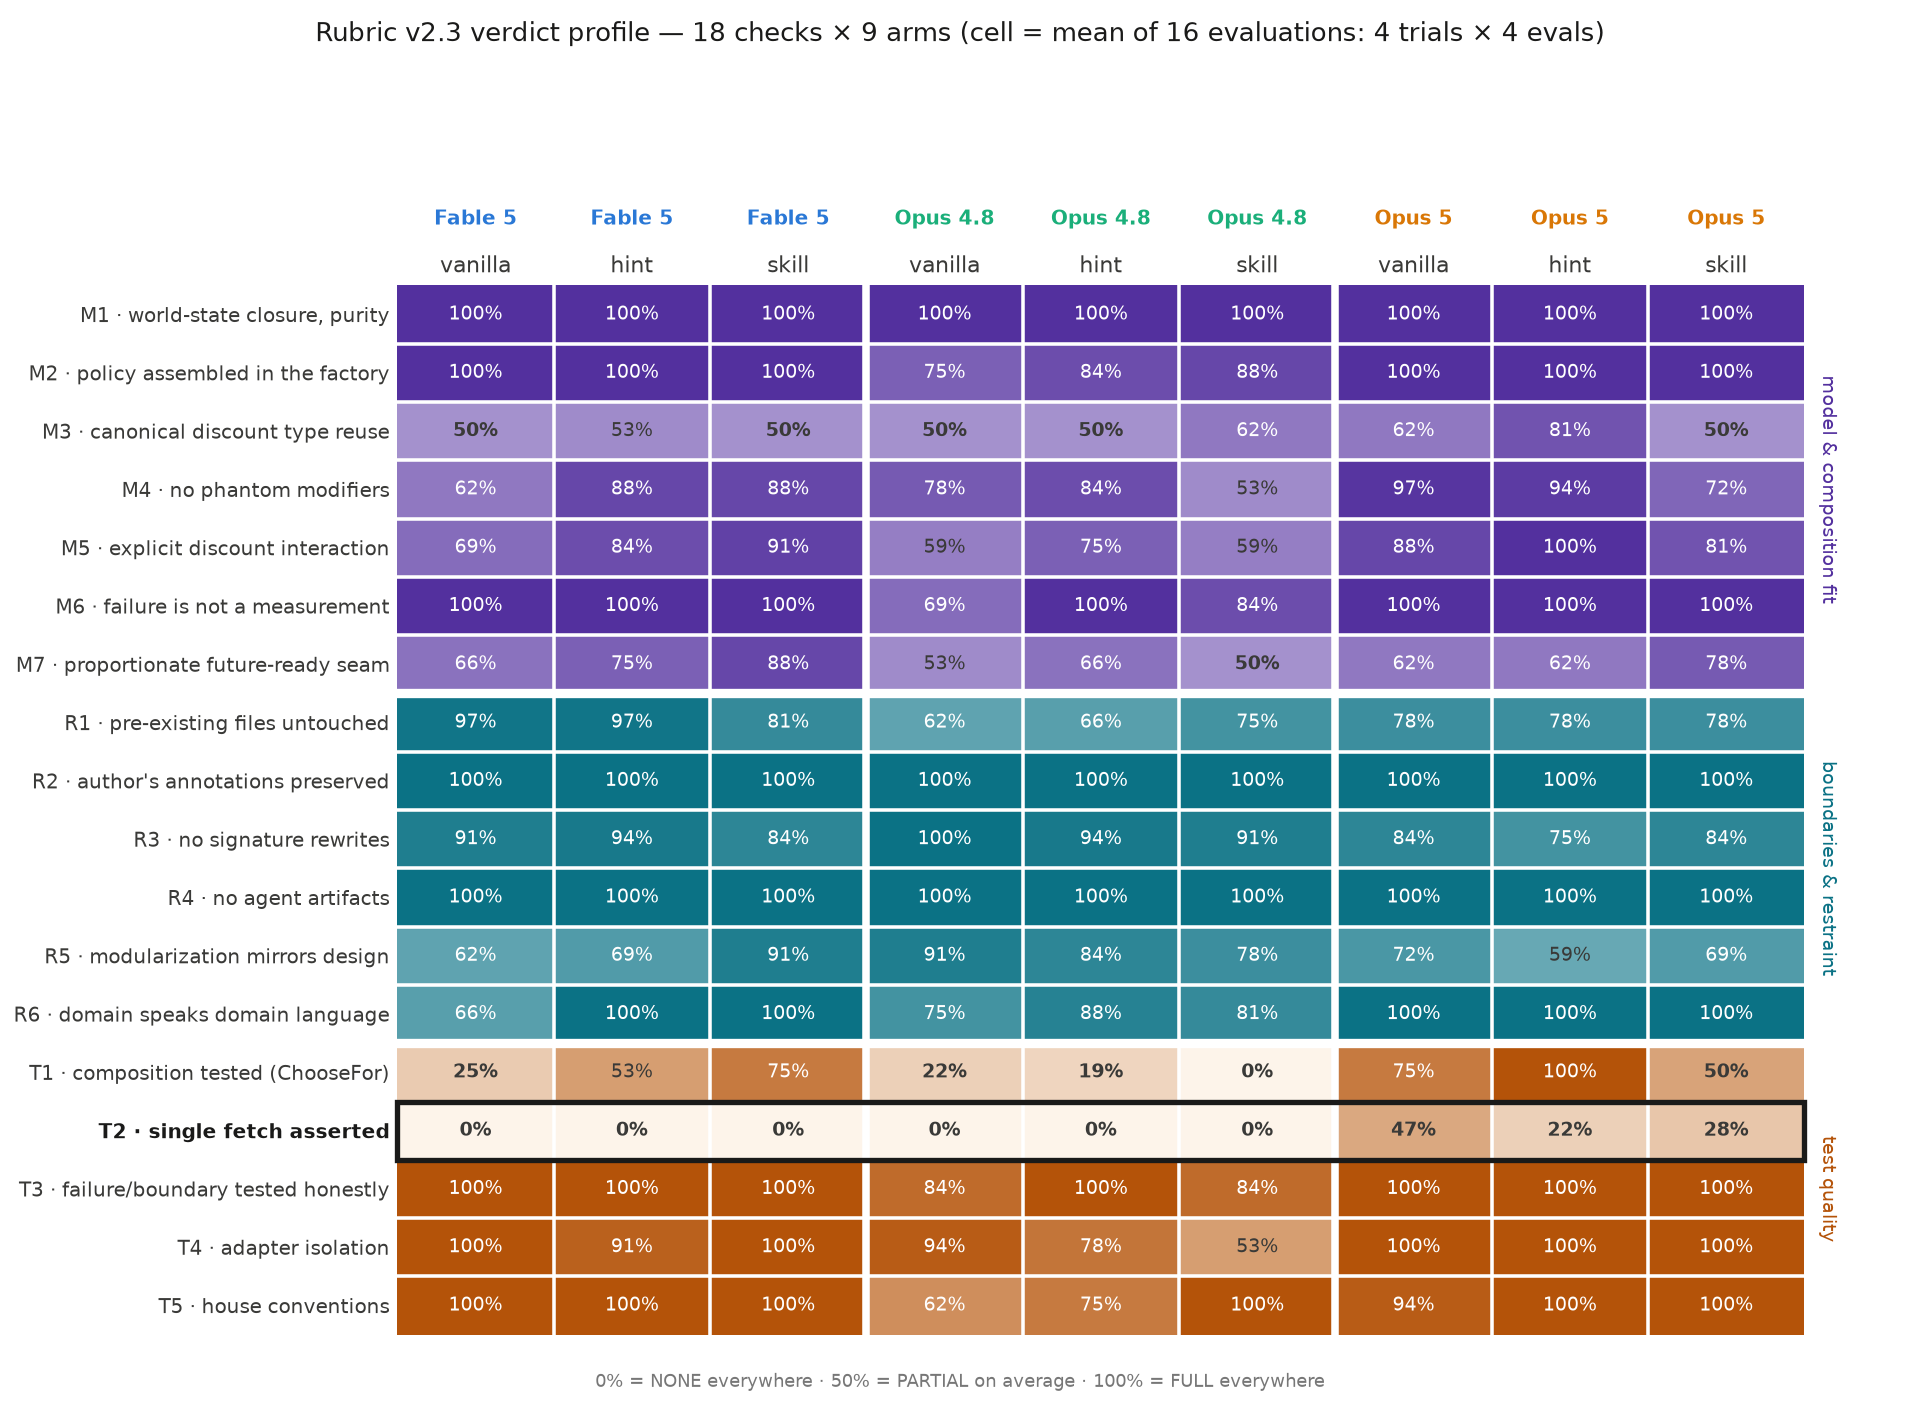
Four findings, each one a change to a routing policy.
The half-price model wins this terrain. Out of the box, with no extra instructions, Opus 5 scored 0.839 against Fable 5’s 0.732, at about two thirds of the run cost. Best configuration against best configuration: 0.866 against 0.808, at 56 percent of the cost. Conclusion: our non-interactive modeling work goes to Opus 5.
The frontier moved unevenly. One behavior, testing how two business rules combine, jumped from 22 to 75 percent of runs between generations. Another, reusing the codebase’s own types, sat near 50 to 60 percent across all three generations and every instruction we tried. Conclusion: human review time concentrates on the checks that never move.
One criterion waited two generations for its model. It is the outlined row in the chart above: “single fetch asserted” - a test that proves the weather service is called at most once per price calculation, so the system never quietly starts hammering an external API. No model met this check in 96 evaluations across two generations: zero percent, every model, every instruction. Opus 5 is the first to start meeting it, unprompted, in about half of its runs. A benchmark can hold standards that today’s models fail, and then tell you precisely when a generation arrives that starts meeting them. Conclusion: keep the checks nobody passes. They are your early warning system for generational jumps on your own work.
Instructions age with the frontier. A heavyweight instruction file that added 0.076 to Fable 5’s score subtracts 0.054 on Opus 5. Conclusion: re-measure your prompt investments on the releases you plan to adopt, instead of carrying them forward on faith.
What this does not prove
This is one task family and four runs per combination, judged by models in their turn; we audited that panel at the generation boundary before trusting scores across generations. The claim is not “Opus 5 is better at domain modeling”. The claim is smaller and more useful: we now know where one of our recurring tasks sits on three frontiers, and that knowledge cost about an evening per model. Interactive coding may genuinely be Fable 5’s terrain. We measured a different point. That is exactly the lesson.
The recipe
You can draw this map for your own work in an evening:
Pick one recurring task with real economic weight.
Freeze its inputs, so every model starts from the same point.
Write down what “done well” means, as checks someone else could apply.
Run the candidate models on it a few times each.
Record the estimated API cost of every run, caching included.
Put cost on one axis, quality on the other, and look.
Steps 1 to 3 do not have to start from a blank page. NASDE has skills that draft the benchmark for you: from a task description, or by mining your git history for problems your team already solved. Treat the generated checks as a draft, and calibrate them before you trust the numbers. NASDE makes that part easy too: every run may arrive as a pull request with the judges’ verdicts as inline comments on the exact lines, so calibration is normal code review: you comment on what the judge got wrong, and those comments become edits to the checks.
Then re-run on the releases that matter to you, because the frontier moves. Not on every release: that would cost more than it teaches. A good trigger is a release you are actually considering, a price change, or a claim that touches your kind of work. The first pass answers “which model should do this work today”. Every later pass answers “did the new release change that”, before the invoice does.
Two sides of learning
The frontier is jagged, invisible, and moving. Public maps show averages. The most important map of your terrain is the one you draw yourself, mostly in your mind.
Learning how AI works is becoming a core part of being a technical professional. Like every part of the craft worth keeping, it can be understood, controlled, and automated instead of guessed. That learning has two sides. This article was about the first: how models work on your tasks, which model does which kind of work, and at what price. The second side is learning how the model did the work: the way it made its choices and implemented the changes. That side deserves its own articles, and we will come back to it.
If this article was useful, subscribe. The next ones will cover the second side of the learning: how the models did the work.
If you would rather have this done with you: mapping your models’ jagged frontier on your own codebase and getting your AI costs under control is work we do as a service. Tell us how to reach you.
More about us: noesis.vision